Insights & Research
Exploring the confluence of frontier AI theory and the engineering realities of shipping it. Field notes, benchmarks, and the occasional opinion.
Laya and RLCD: fast decisions for AI workflows
How typed questions, encoder models, and probability-focused training can move bounded AI judgments into ordinary software.
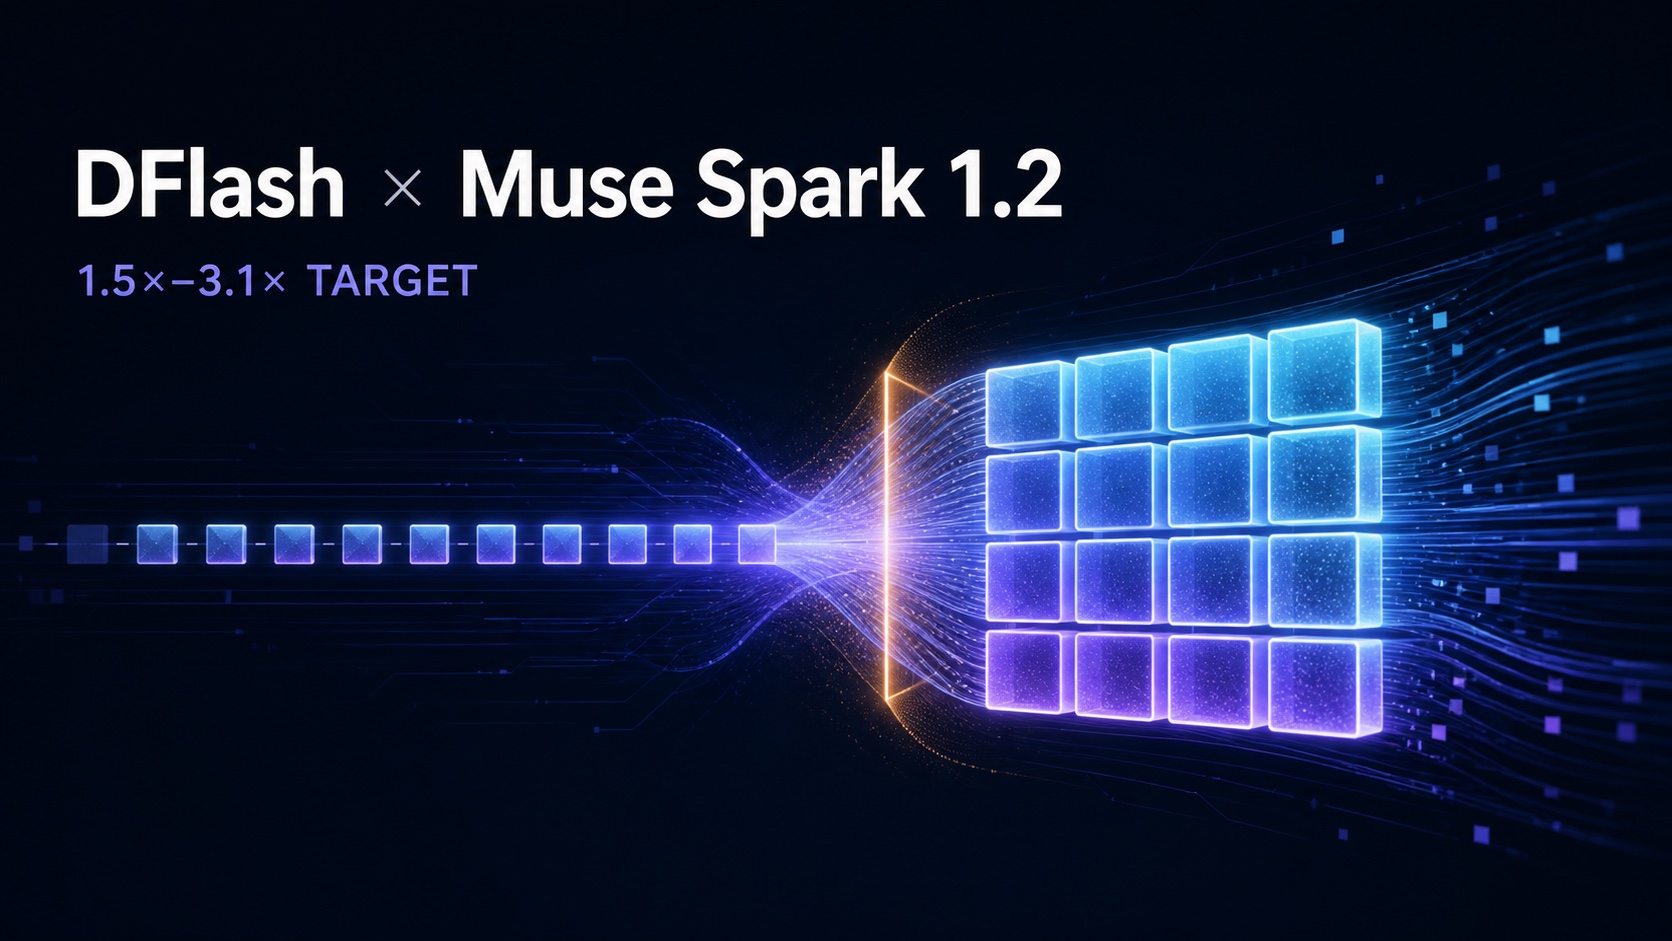
DFlash explained: how block-diffusion drafting makes LLMs generate faster
A visual walkthrough of DFlash architecture, Apple Silicon and RTX execution, and what a Muse Spark integration would actually require.
INT8 post-training quantization without tears: a production checklist
INT8 PTQ in prod is a workflow, not a switch. The six steps we run before any model ships at reduced precision.
Why your AI roadmap should be three lanes, not one
Research, integration, and operations move on different clocks. Treating them as one program is how teams stall.
Evaluating retrieval: beyond top-k accuracy
The metrics that actually correlate with downstream LLM quality, and the ones the leaderboards keep rewarding instead.
Notes from the lab, in your inbox.
Roughly monthly. Engineering, no marketing.